ZB-Lab
We are passionate about data and future-oriented research services.
The ZB-Lab is an interdisciplinary team comprising data librarians, software developers and machine learning engineers. We are based in the Innovation Department and work closely with the ZB Library IT services. To explore the potential of new data applications – in particular the use of artificial intelligence – we engage in dialogue with researchers and carry out joint projects with partner institutions.
At the ZB-Lab, our aim is to improve the visibility and accessibility of the ZB’s digital collections. We want to encourage researchers to use our metadata and digitised materials more extensively. To this end, we experiment with our data, build prototypes and develop new services. We support researchers in finding relevant data, building corpora and transforming data into suitable formats.
We use machine learning methods for data processing. We place particular emphasis on thoroughly verifying the results and ensuring quality. We work transparently, are actively committed to Open Science, and share our data and solutions on GitLab.
News
Get in touch!
We are keen to hear from researchers and other users to better understand their needs and incorporate their feedback into our work. Are you a researcher in the digital humanities or other humanities disciplines? If so, share your perspective and help shape our developments. We would also be happy to support your digital research projects.
ZB-Lab
Projects
Swiss Google Books for Research – Searching historical works by genre
As part of the ‘Swiss Google Books for Research’ project, over 450,000 volumes from the collections of the Zentralbibliothek Zürich, the University Libraries of Basel and Bern, and the Lucerne Central and University Library have been digitised and are now available, alongside other works, on the new Books as Data research portal.
As many of the historical volumes contain only sparse metadata such as title, author and year of publication, searching for specific genres proves difficult. How can users search specifically for biographies or children’s books under these circumstances?
To improve the discoverability of the more than 750,000 works on Books as Data, the ZB-Lab has developed a genre-based search in a collaborative project with the University Library of Basel. To this end, the ZB-Lab trained its own AI model, which automatically classifies historical Swiss prints into one of 19 predefined genres. Users can now search specifically for genres such as dictionaries, academic theses, illustrated books or obituaries of historical figures.
Read our ZBlog post to learn how we developed this automated genre classification.
Zurich address books – Structuring data with AI
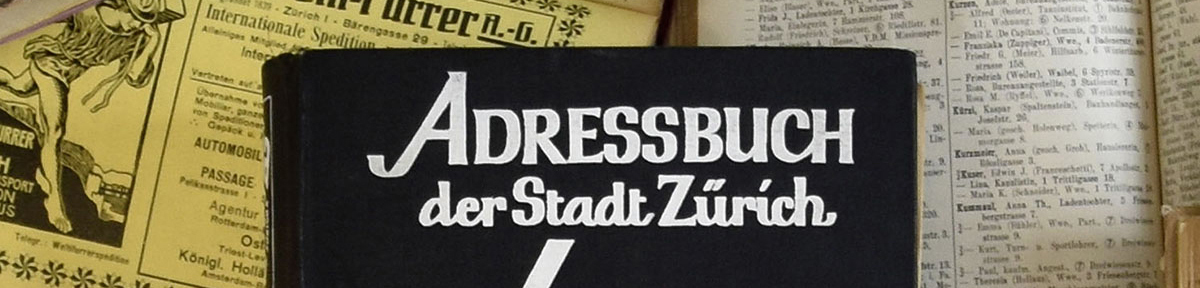
Who used to live in my house? What did the street I live on look like 100 years ago? What shops and institutions were there back then? How has the city changed since then? These questions can actually be answered: the Zurich address books from 1875 to 1998 provide answers to exactly these questions. They are held in the ZB’s collection and are available for everyone to view on the Zurich Open Platform (ZOP).
To unlock the potential of this historical resource, which is of interest to researchers and the public alike, the ZB-Lab entered into a partnership with the SNSF project ‘Multigenerational Social Mobility in Switzerland, 1500–2000’, which is based at the Institute of Sociology at the University of Zurich. The aim of the collaboration is to extract the historical address data from the scanned volumes by the end of 2026 and make it available as a searchable database for both the public and the research community.
AI-assisted cataloguing – music estates and the Zurich Bibliography
The ZB-Lab not only collaborates with external partners, but also supports other departments within the ZB in applying AI to data processing tasks.
For example, the ZB-Lab is helping the Music Department to convert the PDF estate inventories into structured records in the CMI archive database. This benefits users, as they can now easily search the catalogue for the compositions and works of deceased musicians, rather than having to laboriously wade through PDF files and read each entry individually, as was previously the case.
In a similar project, the ZB-Lab is helping the Turicensia Department to incorporate the Zurich Bibliographies (ZüBi), published in PDF format, into the library catalogue and assign them to a subject area. This will make publications from Zurich easier to discover.
Zurich Overnight Visitor Logs – historical guest lists of the City of Zurich
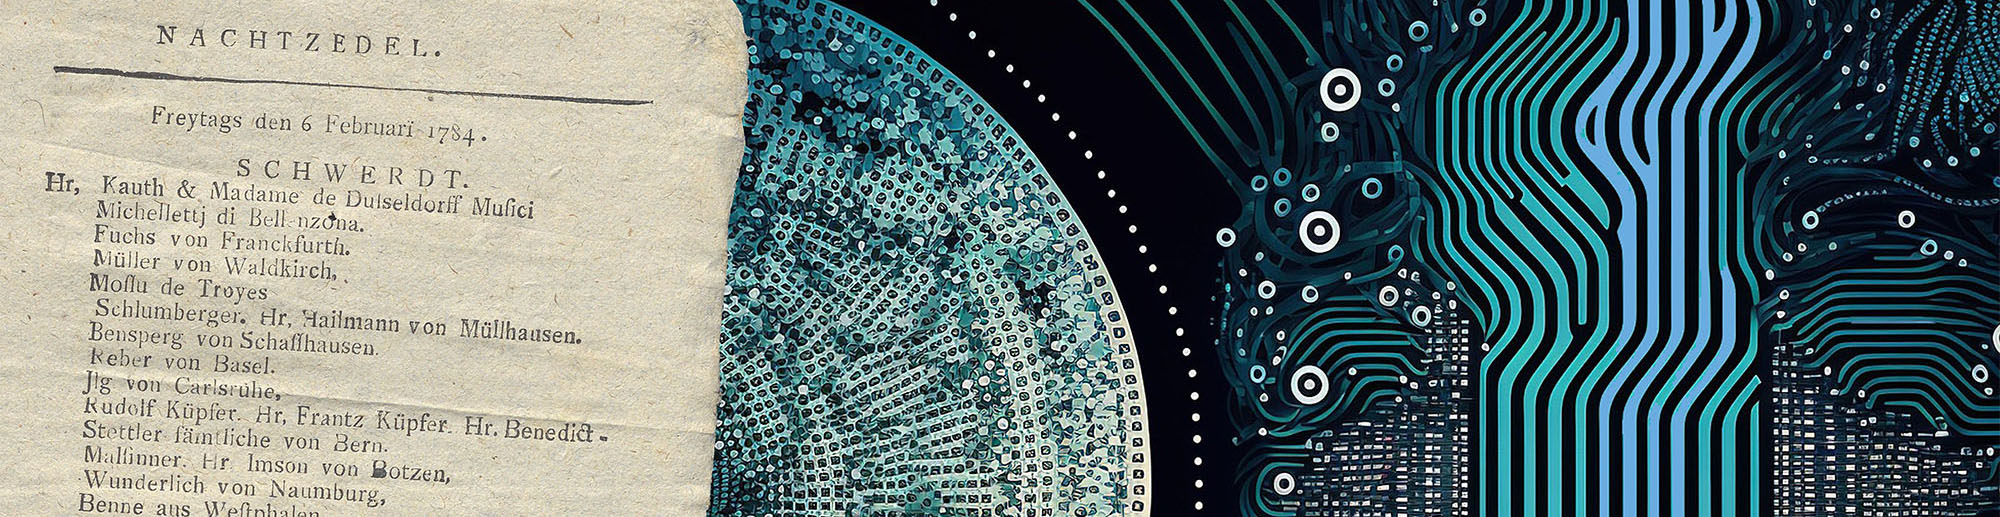
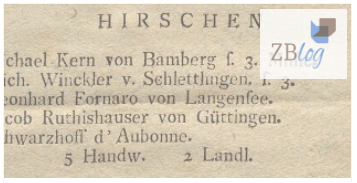
By the light of his oil lamp, the night clerk went from inn to inn, asking guests for their names, places of origin and occupations, thereby leaving behind a unique snapshot of early modern Zurich. The so-called ‘Nachtzedel’ from our manuscript collection (reference number LKR 7, available on e-manuscripta) offer a wealth of insights into mobility, trade and the social networks of the 18th century.
Using large language models, the ZB-Lab has extracted and structured thousands of guest entries, making this fascinating source searchable and analysable for the first time. The resulting dataset enables targeted searches of the ‘Nachtzedel’, providing new insights into travel patterns, occupations and social networks in Zurich at the end of the 18th century.
In our ZBlog post, we describe how we used AI to process and structure the data. The structured dataset is available on Zenodo for reuse. Our interactive dashboard also provides initial exploratory insights into this unique data source.
ZBot – an AI chatbot for the Zentralbibliothek Zürich
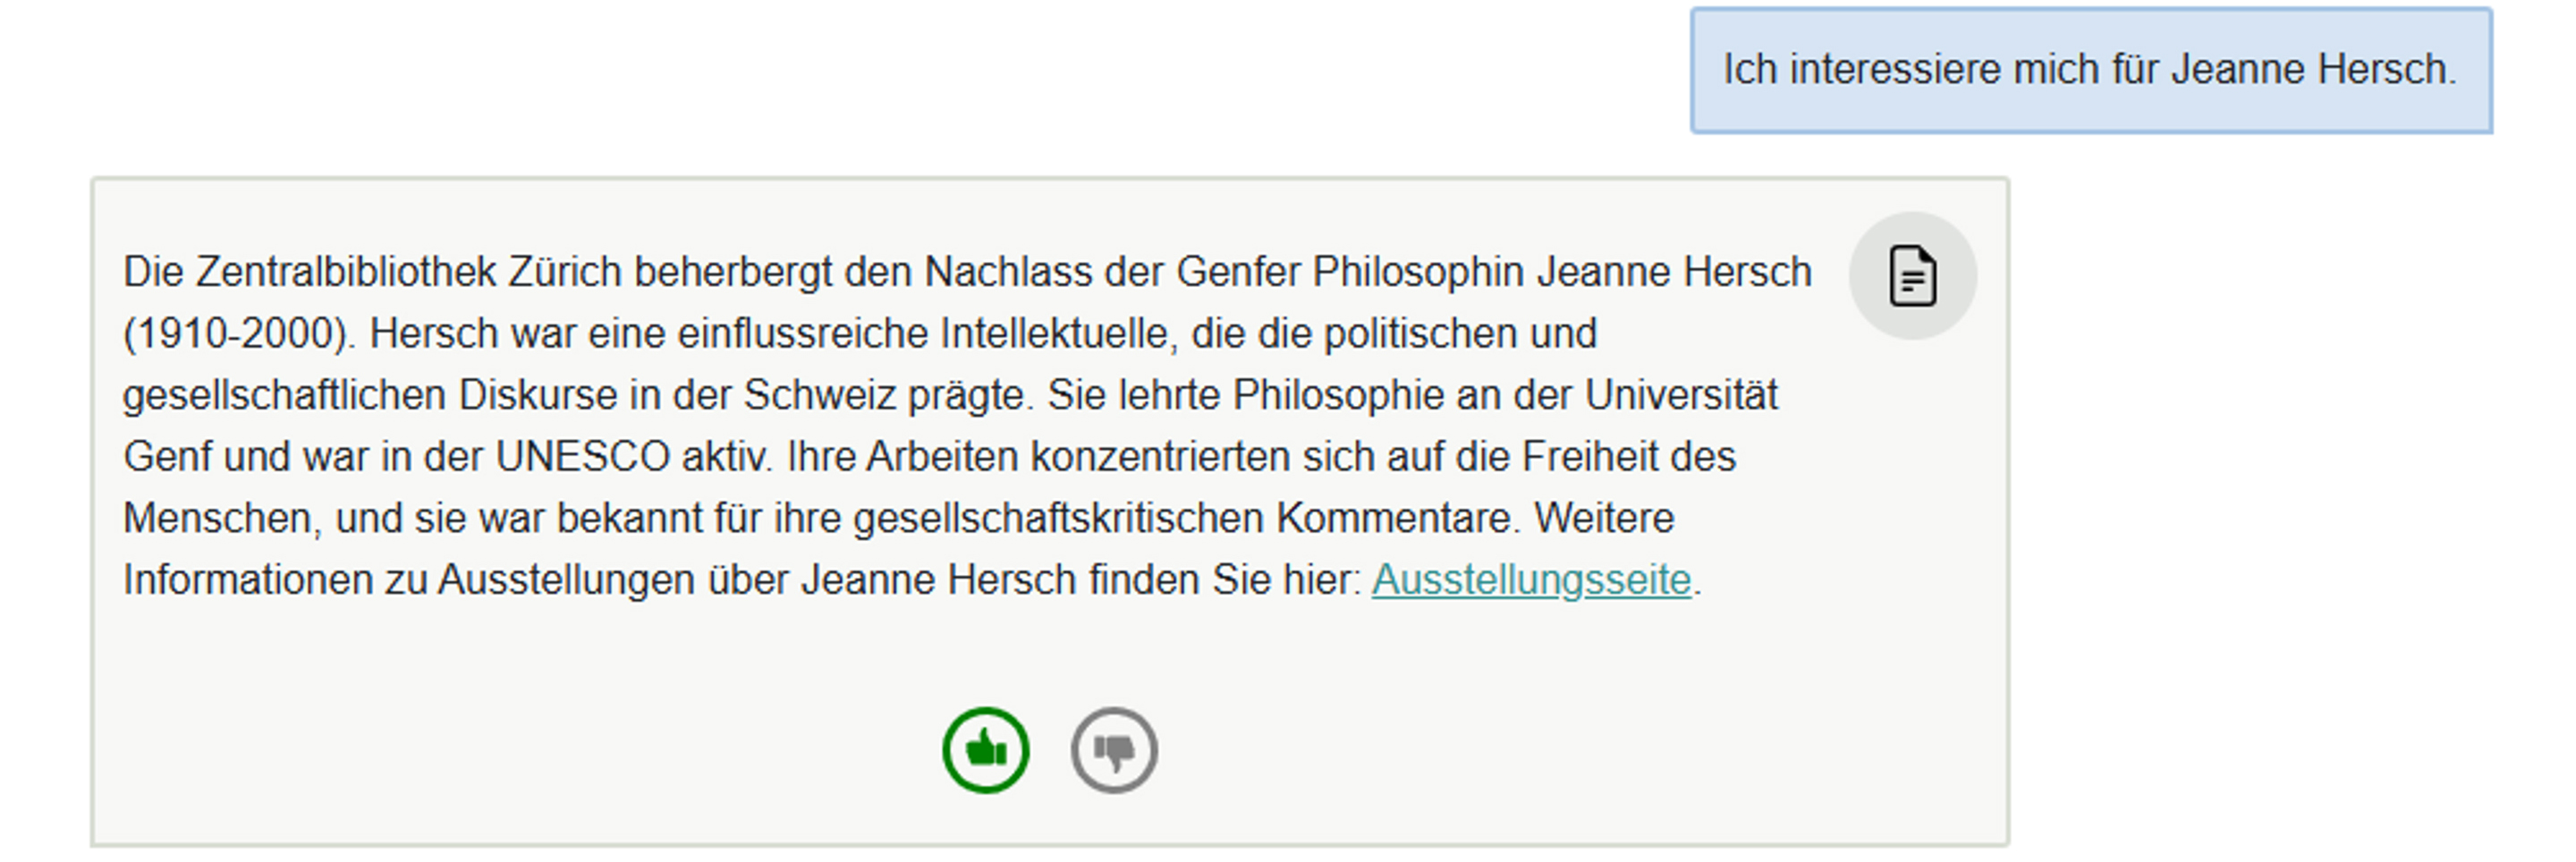
In 2024, the ZB-Lab developed a chatbot prototype capable of answering questions about the ZB. The experiment aimed to explore the potential of AI in everyday library work and to test how reliable, transparent and verifiable the answers provided by such a system are.
The prototype combined a knowledge base comprising texts from the ZB’s website with large language models. These models drew on the knowledge base to generate context-aware answers to user questions. To ensure transparency and traceability, users were able to view the text sections on which the chatbot’s answers were based.
The project provided valuable insights into the possibilities and limitations of AI-powered chatbots. Although the prototype will not be developed further, the experiment lays a solid foundation for future applications and demonstrates how libraries can test new technologies in a considered and responsible manner. Read more about the experiment in the ZB Annual Report 2024.
swisscollections download – easy access to data for researchers
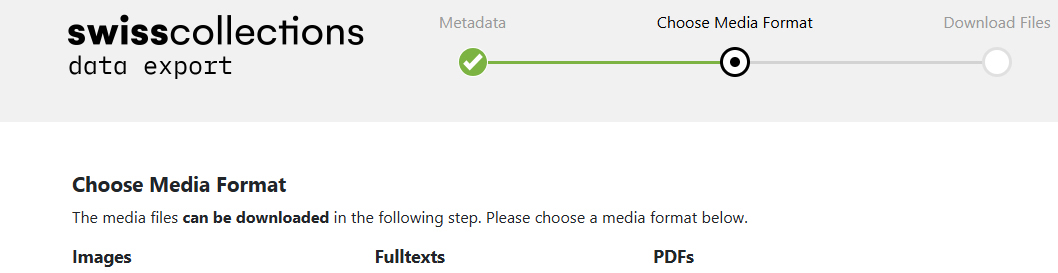
We repeatedly observed researchers using web-scraping scripts to collect library data. This is not only cumbersome and inefficient, but it also often has a negative impact on data quality. At the same time, we were aware that we publish our data on many different platforms. We therefore set out to create a central hub where researchers could easily find relevant documents using high-quality metadata.
Working with the swisscollections association, the ZB-Lab turned its internal ‘OneAPI’ prototype into a new data export feature for the swisscollections catalogue, giving researchers easy access to metadata and digitised holdings from 14 libraries and archives.
The swisscollections catalogue is more than just a search tool: the results list can be exported straight away in various formats – not only as metadata, but also with links to the corresponding digitised holdings. An additional tool also allows images, full texts and PDFs to be downloaded directly to your hard drive.
- How does it work? We’ll show you in this video.
- How does it benefit researchers? We explore this perspective in the ZB Annual Report 2024.
- How was it developed? We report on the ‘making of’ in our ZBlog post.
ZB-detektIIIF and ZB-Viewer – Collect, store and share digitised materials
Using the International Image Interoperability Framework (IIIF), researchers worldwide can collect digitised materials from different institutions and bring them together in our ZB Viewer (Mirador Viewer). With the ZB-detektIIIF browser plug-in, you can automatically identify IIIF-compliant digitised materials and add them to an IIIF collection with a single click. In our beta version, you can also save such collections permanently on GitHub, making them easy to reference and cite (log in via GitHub Octocat).
Furthermore, you can open, compare and analyse as many digitised items as you like from e-manuscripta and e-rara side by side directly in the ZB Viewer – via the ‘Mirador Viewer’ button available in each record's IIIF section.
- Learn how to collect sources with DetektIIIF.
- Open the ZB Viewer (Mirador Viewer).
- Explore the advanced features of the Beta Viewer, including the ability to save your own IIIF collections on GitHub.
Events
Find all upcoming ZB-Lab events in our events calendar.
Don’t want to miss any future events? – Stay up to date and subscribe to our ZB newsletter!
Summer School 2026: Longue Durée digital
How can cultural phenomena and discourses be studied over long periods of time? There are often methodological and practical hurdles between the research question and the text corpus required to address it – and this is precisely where our Summer School in June 2026 offered practical support. Participants were guided through the entire workflow, from building and exploring a text corpus to annotating relevant text passages. The programme also included evening lectures by Sophie Mützel and Lukas Posselt, who explored these topics in greater depth. The slides and Colab notebooks are available on GitLab.
Lecture: From Books to Bytes
 The topics of our 2025 Summer School attracted so much interest that we were invited by the NFDI4Memory consortium’s ‘From Books to Bytes’ lecture series to share our experiences with a wider audience. On 23 January 2026, Sarah Kiener, a software developer and machine learning expert at ZB-Lab, presented our approach to processing historical sources using large language models. The online workshop, entitled ‘From digitised material to structured data’, was exceptionally well attended, attracting 124 participants.
Workshop: Metadata in the Humanities
 For several years now, libraries, archives and museums have increasingly made the metadata of their collections available to researchers: as a result, library catalogues, archive databases, finding aids and letter registers are themselves becoming subjects of research. What challenges does this pose for institutions and researchers? And which models and approaches have proved effective in practice? The workshop provided answers to these questions.
Summer School 2025: From Source to Dataset
From 2 to 3 September 2025, we showed historians and humanities researchers with an interest in digital methods how serial sources such as index cards, registers or lists can be converted into structured datasets using GPT – from prompt design and data extraction via the Python API to quality assurance with OpenRefine. Our own Nachtzedel dataset served as the basis for the practical exercises. Two public evening lectures and a panel discussion rounded off the fully booked Summer School. Most sessions were recorded.
GLAMhack 2024
How does one create a solid data foundation for sophisticated historical analyses? With this question in mind, colleagues from the ZB-Lab and the University Library of Zurich travelled to Lucerne for the anniversary edition of GLAMhack. They brought with them two datasets: the ‘Nachtzedel’, guest registers from Zurich’s hotels and inns dating from 1780 to 1818, and the ‘Promptuarium genealogicum’, seven volumes of genealogical records on Zurich families prior to 1825. Two teams enthusiastically developed tables, graphs and visualisations – an inspiring experience, both for the results it produced and for its collaborative spirit.
Learning resources
Structuring historical sources with GPT
We have turned the materials from the 2025 Summer School ‘From Source to Dataset’ into an e-learning module and made them available on YouTube. Anyone interested can work through individual modules or the entire course.
The course provides an accessible introduction to how language models work, along with practical strategies for writing effective prompts. It also covers methods for evaluating and validating AI-generated outputs, an essential step when the resulting data is intended for further research.
IIIF explained
To help researchers get started with the International Image Interoperability Framework (IIIF), we produced a series of video tutorials as part of our very first ZB-Lab project in the winter of 2020/21. These cover everything from basic IIIF functions and cross-platform searches for digitised materials to the fundamentals of creating your own IIIF manifests. The tutorials are primarily aimed at researchers in the humanities who work with digitised materials.